 tokensaver
A local MCP server that turns web pages, PDFs, Office files and JSON into compact, LLM-ready text — so your coding agent spends its context on content, not markup.
Runs on your machine as a stdio MCP server. Nothing is sent anywhere except the requests to URLs you ask for — no telemetry, no API keys, and it never calls an LLM itself.
One Go binary. PDF extraction uses PDFium compiled to WebAssembly inside the binary. Chrome is used only if installed, for JS-only pages.
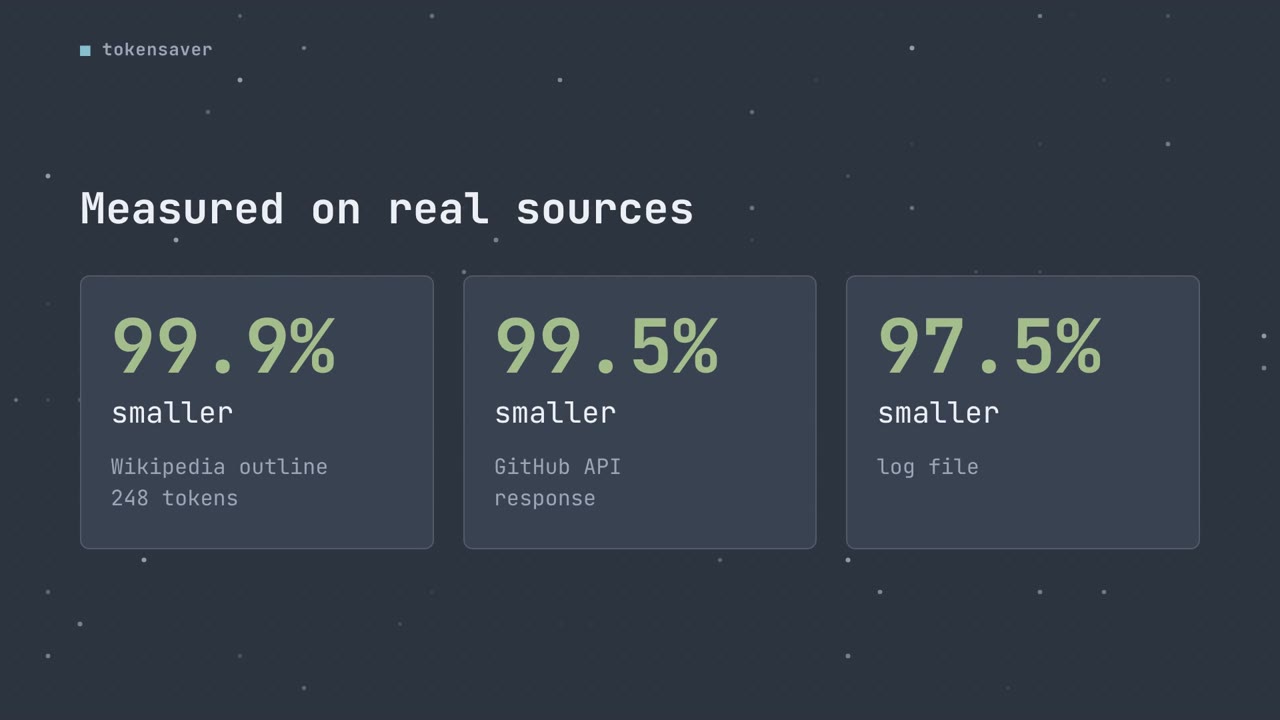
Clean Markdown or shrunk JSON, paged with an outline so your agent reads just the part it needs. Inspired by Microsoft MarkItDown, rebuilt in Go around one goal.
On Windows, or not using Homebrew? Grab an archive from Releases.
Installing another way, or connecting Cursor, Claude Desktop, or another MCP client? See Docs → Install and Docs → Connect it to your agent. Once it is running, Docs → Usage shows what to ask for.
Install, configuration, both tools, and security notes — reorganized from the README into a browsable reference.
Homebrew, release archives, plus the optional Chrome dependency.
Web pages, PDF, DOCX, XLSX, PPTX, diffs, and directories → Markdown.
What tokensaver can read, and what it never does.